How I Built an AI Agent for my Portfolio (Yabasha.dev) using Laravel & Next.js
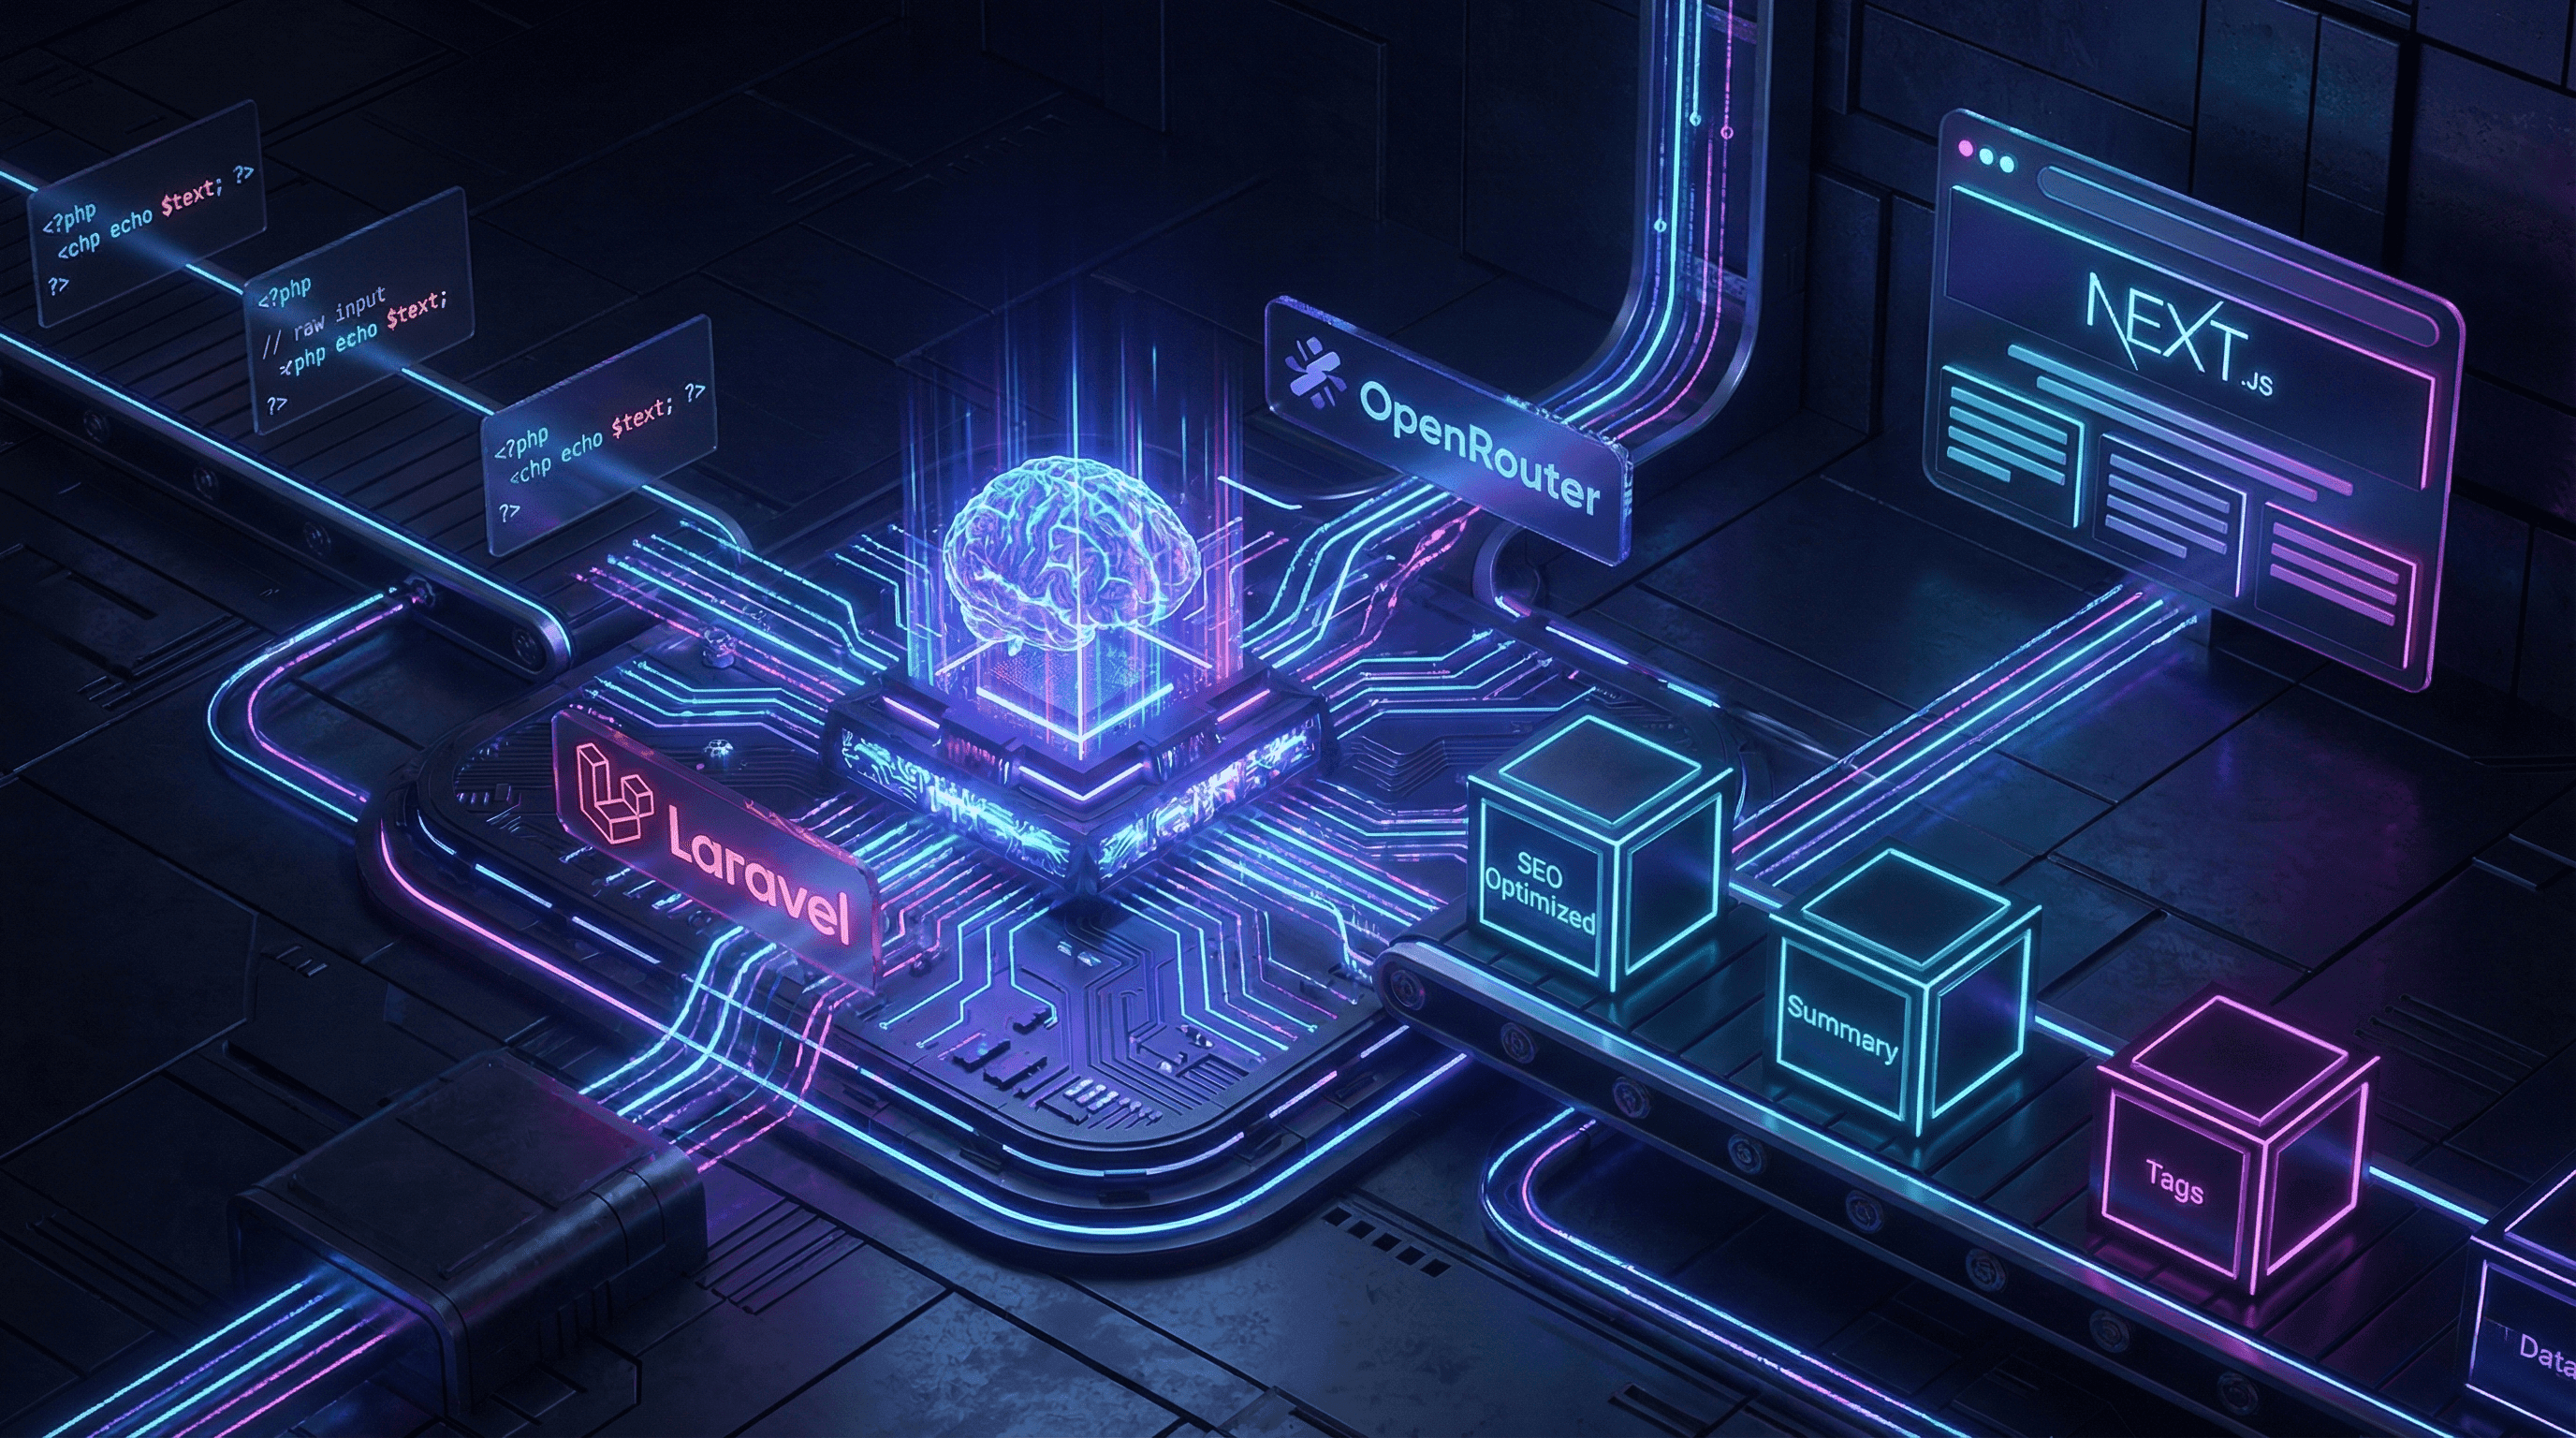
yabasha.dev generates its own SEO metadata from one queued job. PostObserver checks seven fields after every save and dispatches GeneratePostSeoJob when any is empty. The job calls one active OpenRouter model through PostAiService, clamps the summary to 60 words, and falls back to a heuristic that needs no model at all. There is no multi-step agent.
9 min read · 1,783 words
This post is about this site, so every claim in it is checkable. I checked them all, and most of the original ones failed.
I published a version of this in early 2026 describing a five-step agent: fetch the draft, generate metadata, run an SEO pass on a second model, validate, publish. It had a benchmark table pricing five models per task, a cost ledger, and a Filament widget showing thirty days of spend.
Almost none of that is in the repository. There is no FetchDraftJob, no GenerateMetadataJob, no AiCall model, no agent_runs table and no spend widget. I described the system I meant to build.
The agent I wrote about had five steps, per-task model routing and a cost ledger. The one that survived has one step, one model and a heuristic. The simpler one is the one that still runs.
Here is the real thing.
What actually triggers the agent?
Saving a post. There is no review status, no queue button and no cron. An Eloquent observer runs after every save, checks seven columns, and dispatches one job if any of them is empty.
| Column checked | Purpose |
|---|---|
meta_description | The search snippet |
ai_summary_short | The TL;DR block, capped at 60 words |
ai_summary_long | The longer abstract |
ai_topics | Topic labels |
meta_keywords | Keyword list |
primary_keyword | The single target term |
secondary_keywords | Supporting terms |
If every one of those is populated, nothing happens. That single condition is the whole scheduler, and it means the agent is idempotent by accident rather than by design: refill the columns and it stops firing.
The trigger is not "the author asked for metadata". It is "a column is empty". That distinction is why clearing a column is how you ask for a rewrite.
Continue Reading
What does the job actually do?
One model call. GeneratePostSeoJob hands the title and body to PostAiService::analyzeContent(), which builds one prompt, sends one chat request through OpenRouter, and parses one JSON response covering all the fields above.
| Stage | Class | What it owns |
|---|---|---|
| Trigger | PostObserver::saved() | The seven-column check |
| Queue | GeneratePostSeoJob | The timeout, and which fields may be overwritten |
| Prompt and parsing | PostAiService | Building the prompt, decoding JSON, clamping output |
| Transport | OpenRouterService | Model selection, HTTP, failover |
| Catalogue | AiModel | Which model is active |
Five classes, one call. The earlier version of this post split that into five queued steps because five steps sound like an agent. They are not free: each boundary is a place the run can die halfway with some columns written and some not.
Why is there only one active model?
Because choosing per task means maintaining a routing table, and the routing table was the first thing I deleted. AiModel::active()->first() returns one row, and that row's request_id is the model for every call on the site.
The catalogue itself is synced from OpenRouter and stores more than the id.
| Field | What it holds |
|---|---|
request_id | The model string sent to OpenRouter |
context_length | Token window |
pricing_prompt, pricing_completion | The vendor's list price |
estimated_speed, actual_speed | Expected against measured throughput |
is_active | Exactly one row carries this |
Those price columns are the vendor's published rates, not what I spent. Nothing in this repo records the cost of a call. A post that claimed an average cost per post was quoting a number no table holds.
If you want the version with real cost attribution, it is the client system in cutting LLM API costs 60%, where every call was traced before anything was optimised.
What happens when the active model disappears?
OpenRouter retires models, and the failover for that is the one piece of real agent machinery here. It is one level deep and it fires on unavailability, not on a retry count.
OpenRouterService::chat() sends the request with the active model. If the response fails and the error means the model is gone, it deactivates that row, notifies the admin, and resends with the environment fallback model. If that also fails, it logs and returns null.
The failover is not a retry ladder across three vendors. It is one swap, triggered by the model being retired rather than by the request being slow.
That is smaller than what I described before, and it covers the failure that has actually happened to me.
What runs when the model returns nothing usable?
A heuristic that calls no model at all. Three different failures collapse into the same path, and none of them reach the caller as an exception.
| Failure | What analyzeContent() does |
|---|---|
| Null response, including a missing API key | Logs a warning, returns fallbackAnalysis() |
| Response does not decode as JSON | Logs the decode error, returns fallbackAnalysis() |
| Anything throws while processing | Logs the exception, returns fallbackAnalysis() |
fallbackAnalysis() reads the post and produces a summary, an excerpt and a description by truncation and sentence splitting. It is unglamorous and it always answers.
There is a second fallback underneath that one. If the model answers but omits meta_description, the job calls Post::deriveDescription(), which takes the excerpt, or the body if there is no excerpt. That is why a good excerpt is the best insurance in the whole pipeline.
Why is the model's output clamped before it is saved?
Because the model overshoots the word budget often enough to lose the sentence worth quoting. ai_summary_short is capped at 60 words. The frontend truncates on sentence boundaries, so an over-long summary loses its final clause, and the final clause is usually the one carrying the outcome.
So the same clamp the heuristic uses is applied to the model's answer too. It is a two-line fix for a failure that is otherwise invisible: the field is populated, the type is right, and the most citable sentence is missing.
Schema validation tells you the field arrived. It does not tell you the useful half of the sentence was cut off. That check has to be written by hand.
How long is the job allowed to take?
Longer than the call it makes, which sounds obvious and was not. A single OpenRouter request is allowed 120 seconds. Horizon gives a worker 60.
| Layer | Limit |
|---|---|
| Horizon worker timeout | 60 seconds |
| Horizon retries | 3 |
| Single OpenRouter call | 120 seconds |
GeneratePostSeoJob timeout | 150 seconds |
For a while the job declared no timeout of its own, so it inherited 60 and any post long enough to take the model past a minute was killed mid-request. It wrote nothing and produced no useful error. I wrote that failure up properly in building production AI agents that actually work; the short version is that the job now declares 150 and the comment above it says why.
The retries are Horizon's, not the job's. The published version of this post gave the job $tries = 3 and a three-step backoff array. It has neither.
How does the published page find out?
Through a second job, not through this one. PostObserver also dispatches RevalidateFrontendJob, which posts a cache tag to the Next.js side, and the route calls revalidateTag.
There is a catch worth knowing if you build this. The SEO job writes quietly, without firing the observer again, so regenerating metadata purges nothing. The page waits out its own timer instead. A curl immediately after a run still shows the old value, and I have talked myself into believing a column was dropped on exactly that evidence.
The full protocol, including the acknowledged version I would build if staleness cost money, is in the cache handshake.
What does the admin side actually look like?
Filament 4, with five widgets, none of which are about AI spend.
| Widget | What it shows |
|---|---|
ContentOverviewStats | Counts across content types |
PublishingPipelineStats | What is drafted, scheduled and published |
LatestPostsTable | Recent posts |
NewsletterStats | Subscribers and issues |
UpcomingSpeaksTable | Scheduled talks |
The real controls are artisan commands rather than admin pages: posts:regenerate-summary for one post's TL;DR, posts:apply-revision to write a whole post from a markdown file, and posts:publish-scheduled, which the scheduler runs every minute.
Which versions is this running on?
Read from the lockfiles on 2026-09-21, because the published version of this post was wrong about two of them.
| Piece | Version |
|---|---|
| Laravel | 12.69, PHP 8.4 |
| Filament | 4.12, not 3 |
| Next.js | 16.3.4, not 15 |
| Queue | Horizon on Redis |
| Model access | OpenRouter, one active model |
What is still missing?
Four things, and I am listing them because the previous version of this post claimed three of them were already built.
| Gap | Why it is still open |
|---|---|
| No per-call cost record | The catalogue holds list prices, not spend. I would need one table and one write per call |
| No evaluation set | Nothing checks whether a new model writes better metadata than the old one. Model swaps are judged by reading a few posts |
| No retry on a bad summary | A too-short or off-topic summary is fixed by clearing the column and saving again, by hand |
| No trace across the two apps | Correlating a publish to a purge is still grep. I removed error tracking and log JSON instead |
The architecture around all of this is described in what yabasha.dev actually runs, including the parts I would not ship to a client.
What would I tell someone starting this?
Build the trigger and one call. Nothing else, at first.
The instinct is to design the pipeline, because a pipeline is the interesting part. But a five-step pipeline has four places to die halfway, and on a personal site there is no traffic to justify that risk. One observer, one job, one model and a plain-code fallback covers the whole job of labelling your own writing.
The hard part was never the agent. It is still thinking clearly enough to draft something worth publishing. Everything downstream of that is plumbing, and plumbing should be boring.
The second mistake is never automating anything. That one I did avoid.
Read from the tree on 2026-09-21
apps/web/package.json,apps/backend/composer.jsonfor every version abovePostObserver,GeneratePostSeoJob,PostAiService,OpenRouterService,AiModelconfig/horizon.phpfor the worker timeout and retry countroutes/console.phpfor the scheduled commandsapp/Filament/Widgets/for the widget list
The repository is private, so none of this is a link you can follow. The earlier version of this post said the pipeline was open source and invited readers to go and read it. That was wrong, and it is the correction I most wanted to make.
Questions: @bayyash
Bashar Ayyash (Yabasha)
AI Systems Architect for regulated industries — evals, harness design, AI security.
Bashar Ayyash is an AI engineer and dev lead in Amman, Jordan. 20 years shipping software, 4 years inside a regulated bank building production RAG and agent systems with evals, guardrails and monitoring — in Arabic and English. He writes at yabasha.dev and builds open-source tooling for AI-assisted development.
Newsletter
Practical AI + full-stack insights for MENA builders. No spam.
Related Articles
Graph Engineering Is Mostly Airflow With A New Coat Of Paint
Stop Building Fragile APIs: A Laravel Engineering Blueprint
AI Agents Ate My Boilerplate: What Actually Works in Enterprise Banking
Building Production AI Agents That Actually Work
Read more on the blog
Browse the latest articles or explore the full archive.