4 Models. 12 Days. The Open-Source AI Price War Just Ended — And China Won
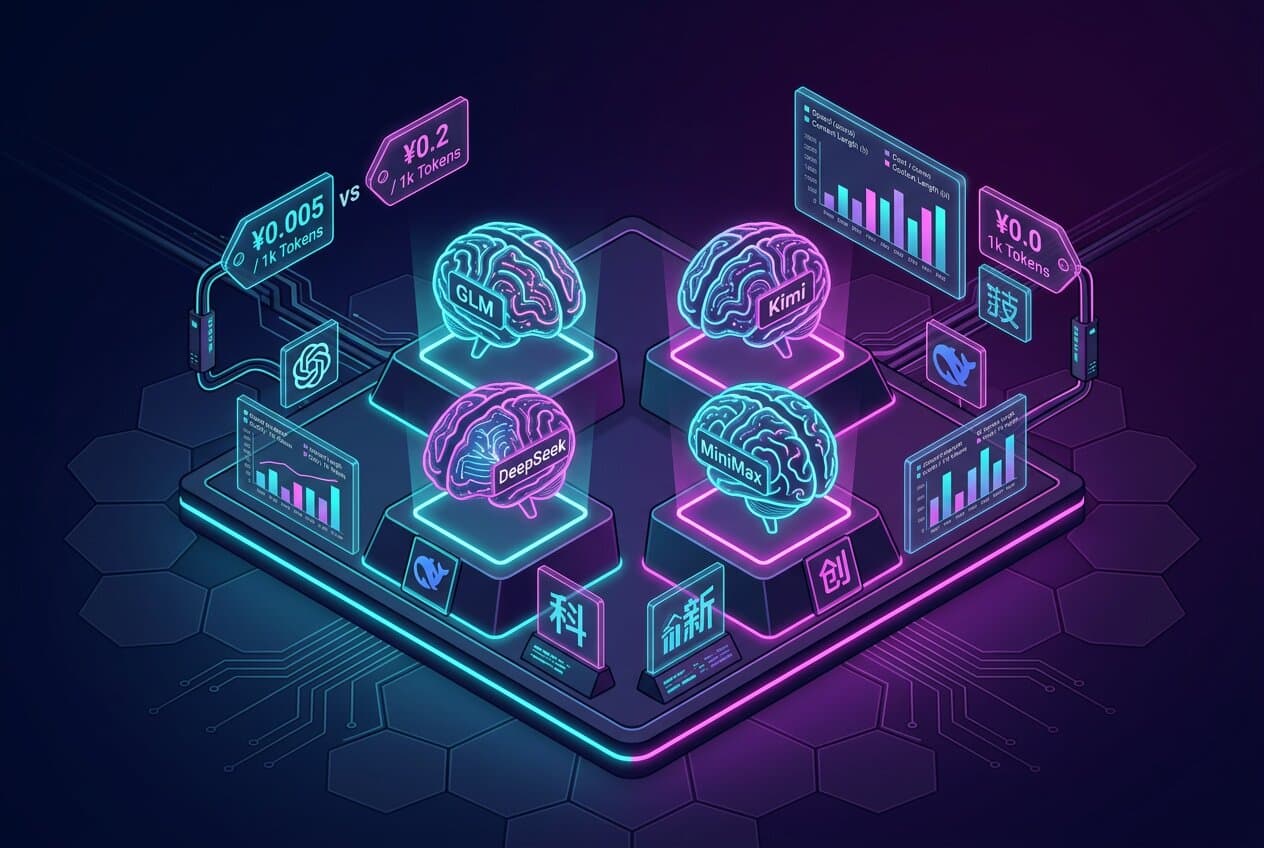
Four Chinese open-weight AI models released in 12 days benchmark within striking distance of Claude Opus 4.6 at 5-25x lower cost.
6 min read · 1,061 words
4 Models. 12 Days. The Open-Source AI Price War Just Ended — And China Won
Last month, four Chinese AI labs dropped competing open-weight coding models in a 12-day window. Each one benchmarks within striking distance of Claude Opus 4.6. Each one costs a fraction of the price. The open-source AI "catch-up" narrative? It's dead.
Here's what happened — and what it means if you're building anything with AI right now.
The April 2026 Tsunami
Between April 7 and April 24, 2026, the following models went live:
| Date | Model | Lab | Key Stat |
|---|---|---|---|
| Apr 7 | GLM-5.1 | Z.AI (Zhipu) | First open-weight #1 on SWE-Bench Pro |
| Apr 20 | Kimi K2.6 | Moonshot AI | Beat GPT-5.4 on SWE-Bench Pro |
| Apr 24 | DeepSeek V4 | DeepSeek | 93.5% LiveCodeBench — highest of any model |
| Mar 18 | MiniMax M2.7 | MiniMax | 10B active params, 56.22% SWE-Pro |
That's not a slow evolution. That's a tectonic shift.
Continue Reading
Kimi K2.6: The Open-Weight King for Coding
Moonshot AI's Kimi K2.6 is a 1-trillion-parameter MoE model with 32B active parameters. It scored 58.6% on SWE-Bench Pro — beating GPT-5.4 (57.7%) and Claude Opus 4.6 (53.4%) on the hardest verified coding benchmark.
The number that matters for production teams: $0.60 per million input tokens. That's roughly 8x cheaper than Opus 4.7 at $5/M.
K2.6 also handles autonomous coding sessions over 12 hours and coordinates up to 300 sub-agents across 4,000+ tool calls. This isn't a model that wrote a function — it's a runtime architecture for shipping code.
Where it shines: Long-running agent loops, multi-file refactors, polyglot projects (Rust, Go, Python).
Where it doesn't: The 256K context window is fine for most work, but monorepo analysis across hundreds of files will hit the ceiling.
DeepSeek V4 Pro Max: The Cost Shock
DeepSeek V4 landed on April 24 and immediately redefined what "frontier-class" costs.
The numbers:
- V4-Pro-Max: 1.6T total params, 49B active, 1M context, MIT license
- LiveCodeBench: 93.5% (highest of any model, period)
- SWE-bench Verified: 80.6% — 0.2 points behind Claude Opus 4.6
- Codeforces Elo: 3,206 (ahead of GPT-5.4's 3,168)
- Output cost: $3.48/M vs Opus 4.6's $75/M
That's a 21x cost reduction at near-identical coding benchmark performance.
The Flash variant is even more absurd: $0.14/M input tokens. For high-volume batch coding workflows, that's a different economic category entirely.
NIST's CAISI evaluation confirmed V4 is "the most capable PRC AI model to date" — though they noted it still lags the Western frontier by about 8 months on certain reasoning tasks. Fair enough. At 1/21st the price, I'll take that trade.
GLM-5.1: MIT License, Frontier Performance
Z.AI's GLM-5.1 made history on April 7 as the first open-weight model to top SWE-Bench Pro at 58.4%. It held that #1 spot for nine days until Claude Opus 4.7 reclaimed it.
754 billion parameters. MoE architecture. MIT license — meaning fine-tune, self-host, redistribute, no questions asked.
On real-world agentic tasks, it scores 1,535 on the GDPval-AA leaderboard, placing it third globally for agentic web development. The Code Arena Elo of 1,530 reflects actual developer preference in head-to-head comparisons.
Pricing: Starting from $0.60/M input tokens (API) or free if you self-host.
The MIT license is the real story here. Enterprise teams that need full weights access without commercial restrictions now have a legitimate frontier-class option.
MiniMax M2.7: The Efficiency Play
MiniMax M2.7 is the dark horse. With only 10B active parameters out of 230B total, it scores 56.22% on SWE-Bench Pro — 94% of GLM-5.1's performance at roughly one-fifth the per-token cost.
At $0.30/M input tokens, it's the cheapest option for high-throughput coding workloads. MiniMax also reported that an internal version of M2.7 autonomously optimized a programming scaffold over 100+ rounds, achieving a 30% performance improvement through self-evolution.
The catch: M2.7's license shifted from MIT (M2/M2.5) to non-commercial. For research, prototyping, and internal tooling, it's excellent. For production products, you'll need an enterprise agreement.
What About Qwen?
Alibaba's Qwen family continues to dominate specific niches:
- Qwen 3.6 Plus leads Terminal-Bench 2.0 at 61.6% with a 1M token context window — the only model in this group that can handle monorepo-scale analysis
- Qwen3-Coder-Next (released May 19) is a lightweight 80B MoE with only 3B active, purpose-built for coding agents at $0.11/M input
- Qwen 3.5-397B-A17B scored 83.6 on LiveCodeBench v6 with only 17B active parameters
Qwen's strategy is clear: own the cost-efficient, open-weight middle ground while closing the gap on flagship performance.
Brand New: Ring-2.6-1T
Just this week, InclusionAI (under Ant Group) released Ring-2.6-1T — a 1-trillion-parameter thinking model under MIT license. It's built for agent workflows, coding, and long-horizon reasoning. Early benchmarks show it surpassing GPT-5.4 and Gemini 3.1 Pro on certain tasks. This one's worth watching.
The Real Story: Price-Per-Quality Has Collapsed
Here's the comparison that changes your budget conversation:
| Model | Input $/M | Output $/M | SWE-bench Verified | LiveCodeBench |
|---|---|---|---|---|
| Claude Opus 4.6 | $15.00 | $75.00 | 80.8% | 88.8 |
| GPT-5.5 | $5.00 | $30.00 | 88.7% | — |
| DeepSeek V4 Pro Max | $0.55 | $3.48 | 80.6% | 93.5 |
| Kimi K2.6 | $0.60 | $2.50 | ~72% (Tier A) | 89.6 |
| GLM-5.1 | $0.60 | $2.00 | ~74% | — |
| MiniMax M2.7 | $0.30 | $1.20 | 78% | — |
DeepSeek V4 Pro Max scores 80.6% on SWE-bench Verified at $3.48/M output. Claude Opus 4.6 scores 80.8% at $75/M output. That's a 21x price gap for 0.2 benchmark points.
For teams running thousands of agentic coding tasks per day, this isn't incremental savings. It's a structural shift in what's economically feasible.
What This Means for Developers
1. The "open-source is two years behind" argument is empirically wrong. GLM-5.1 topped SWE-Bench Pro. DeepSeek V4 matches Opus 4.6 on SWE-bench Verified. Kimi K2.6 beat GPT-5.4. All three are built without Nvidia hardware.
2. The harness matters more than the model. The gap between raw model capability and production outcomes is now determined by your eval discipline, tooling, and reliability instrumentation. Pick the model that fits your workload, then spend more attention on the layer above it.
3. Self-hosting is a real option. GLM-5.1 (MIT), DeepSeek V4 (MIT), Kimi K2.6 (modified MIT), and Qwen3.6-27B (Apache 2.0) all support self-hosting. For teams with latency requirements or data residency needs, this changes the architecture conversation.
4. The pricing gap is 5-25x and widening. Chinese-stack inference runs 5-25x cheaper at frontier capability tiers. As DeepSeek's V4-Flash at $0.14/M input demonstrates, the floor keeps dropping.
Coming Next
- Kimi K3 — teased March 28, expected Q3 2026. 1M context, 3-4T total parameters
- DeepSeek V5 — aggressive cadence continues
- Qwen 4 — Alibaba's annual cycle suggests Q3/Q4 announcement
- GPT-6 — late May to early July 2026, with long-term memory as the headline feature
The next 90 days will be the most competitive window in AI history. If you're not evaluating these models against your actual workloads, you're making architecture decisions based on last year's pricing.
Data sourced from LLM Stats, OpenRouter API, BenchLM.ai, Artificial Analysis, NIST CAISI evaluations, and provider documentation as of May 20, 2026.
Bashar Ayyash (Yabasha)
AI Systems Architect for regulated industries — evals, harness design, AI security.
Bashar Ayyash is an AI engineer and dev lead in Amman, Jordan. 20 years shipping software, 4 years inside a regulated bank building production RAG and agent systems with evals, guardrails and monitoring — in Arabic and English. He writes at yabasha.dev and builds open-source tooling for AI-assisted development.
Newsletter
Practical AI + full-stack insights for MENA builders. No spam.
Related Articles
Why My AI Prompts Are 12 Words Long — And Yours Should Collapse Too
Findable Is Not Chosen — and That Résumé Won't Save You
The $18K Ceiling Breaker: Skills That Actually Move Your Number
Building Production AI Agents That Actually Work
Read more on the blog
Browse the latest articles or explore the full archive.
AI Pricing & Open-Source Model Series
This post is part of a series on AI pricing and open-source model economics.
The May 2026 Open-Weight Shakeup
Full open-weight model landscape analysis
ReadThe Pricing Chasm
Chinese vs Western cost floor analysis
ReadNo Single Model Wins
Practical guide to choosing the right model
ReadThe Collapse of AI Pricing Gravity
Why open-source shattered unit economics by 90-95%
ReadThe Pricing Gravity of AI
Anthropic's $900B valuation and scale economics
Read